YourownAImodel,
onyourownGPUs.
Chooseaready-to-usemodelandgolive.Wehandletheservers,scalingandsecurity.YoujustcallanAPI.

 Why Dedicated Inference

Your model runs on GPUs no other customer touches. Nobody else slows you down, so speed stays steady as you grow.

We set up how your model runs to match how people use it, so answers come back faster and cost less.

We check your model before launch, filter what goes in and out, and test it against real attacks.
How It Works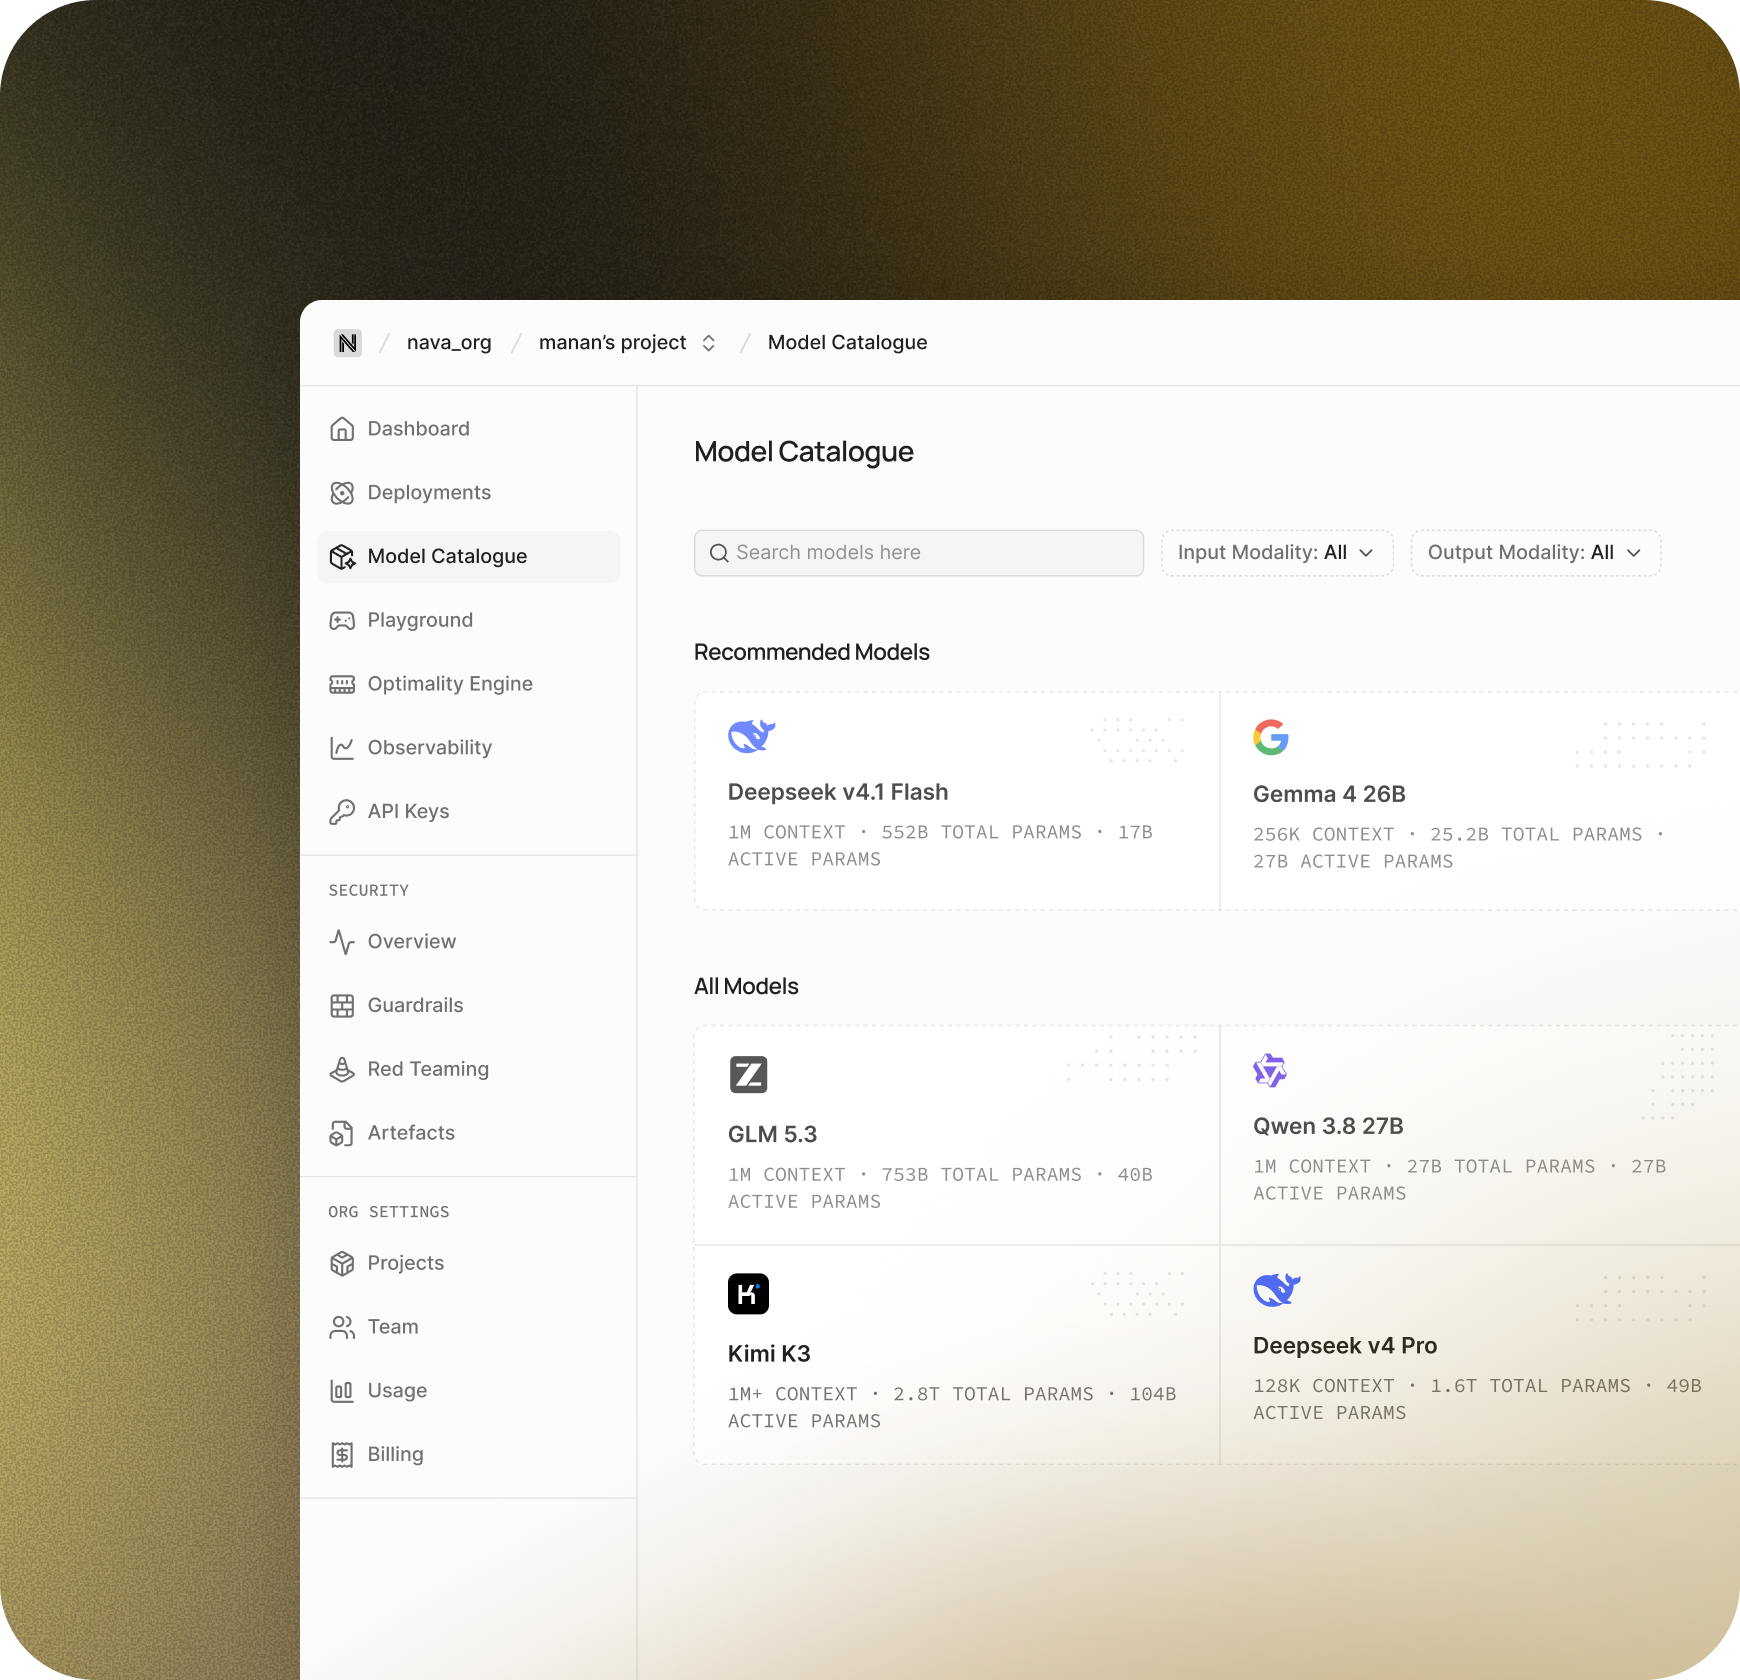
Pick a Model
Browse our tested, safety-checked open models and choose the one that fits your application.
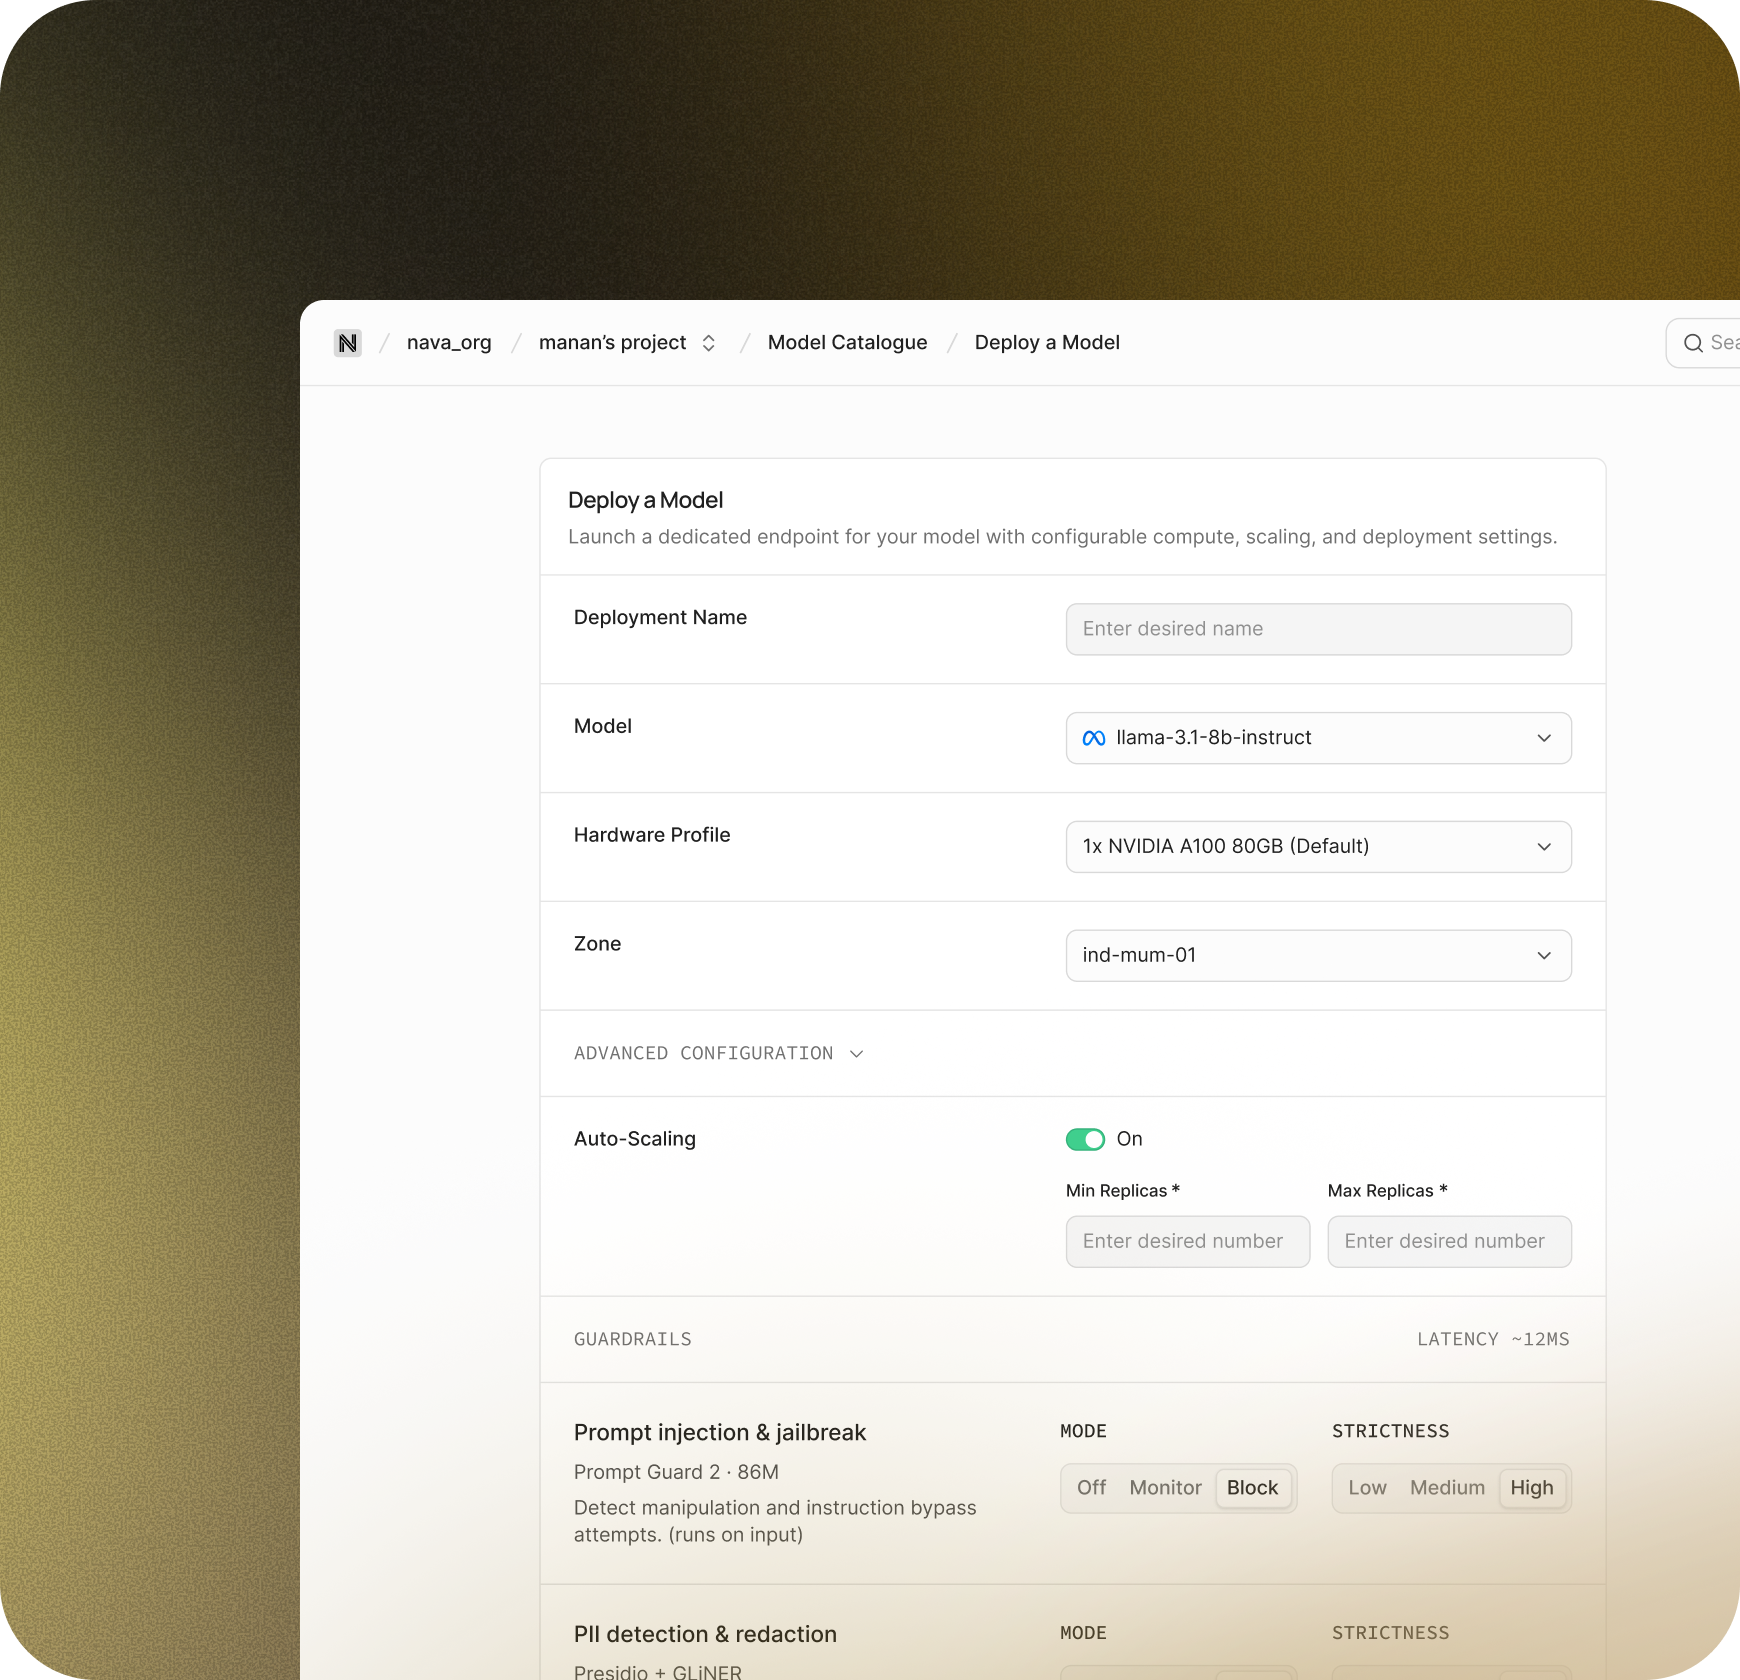
Set It Up
Choose where it runs, how many GPUs it uses, and whether to turn on safety filters.
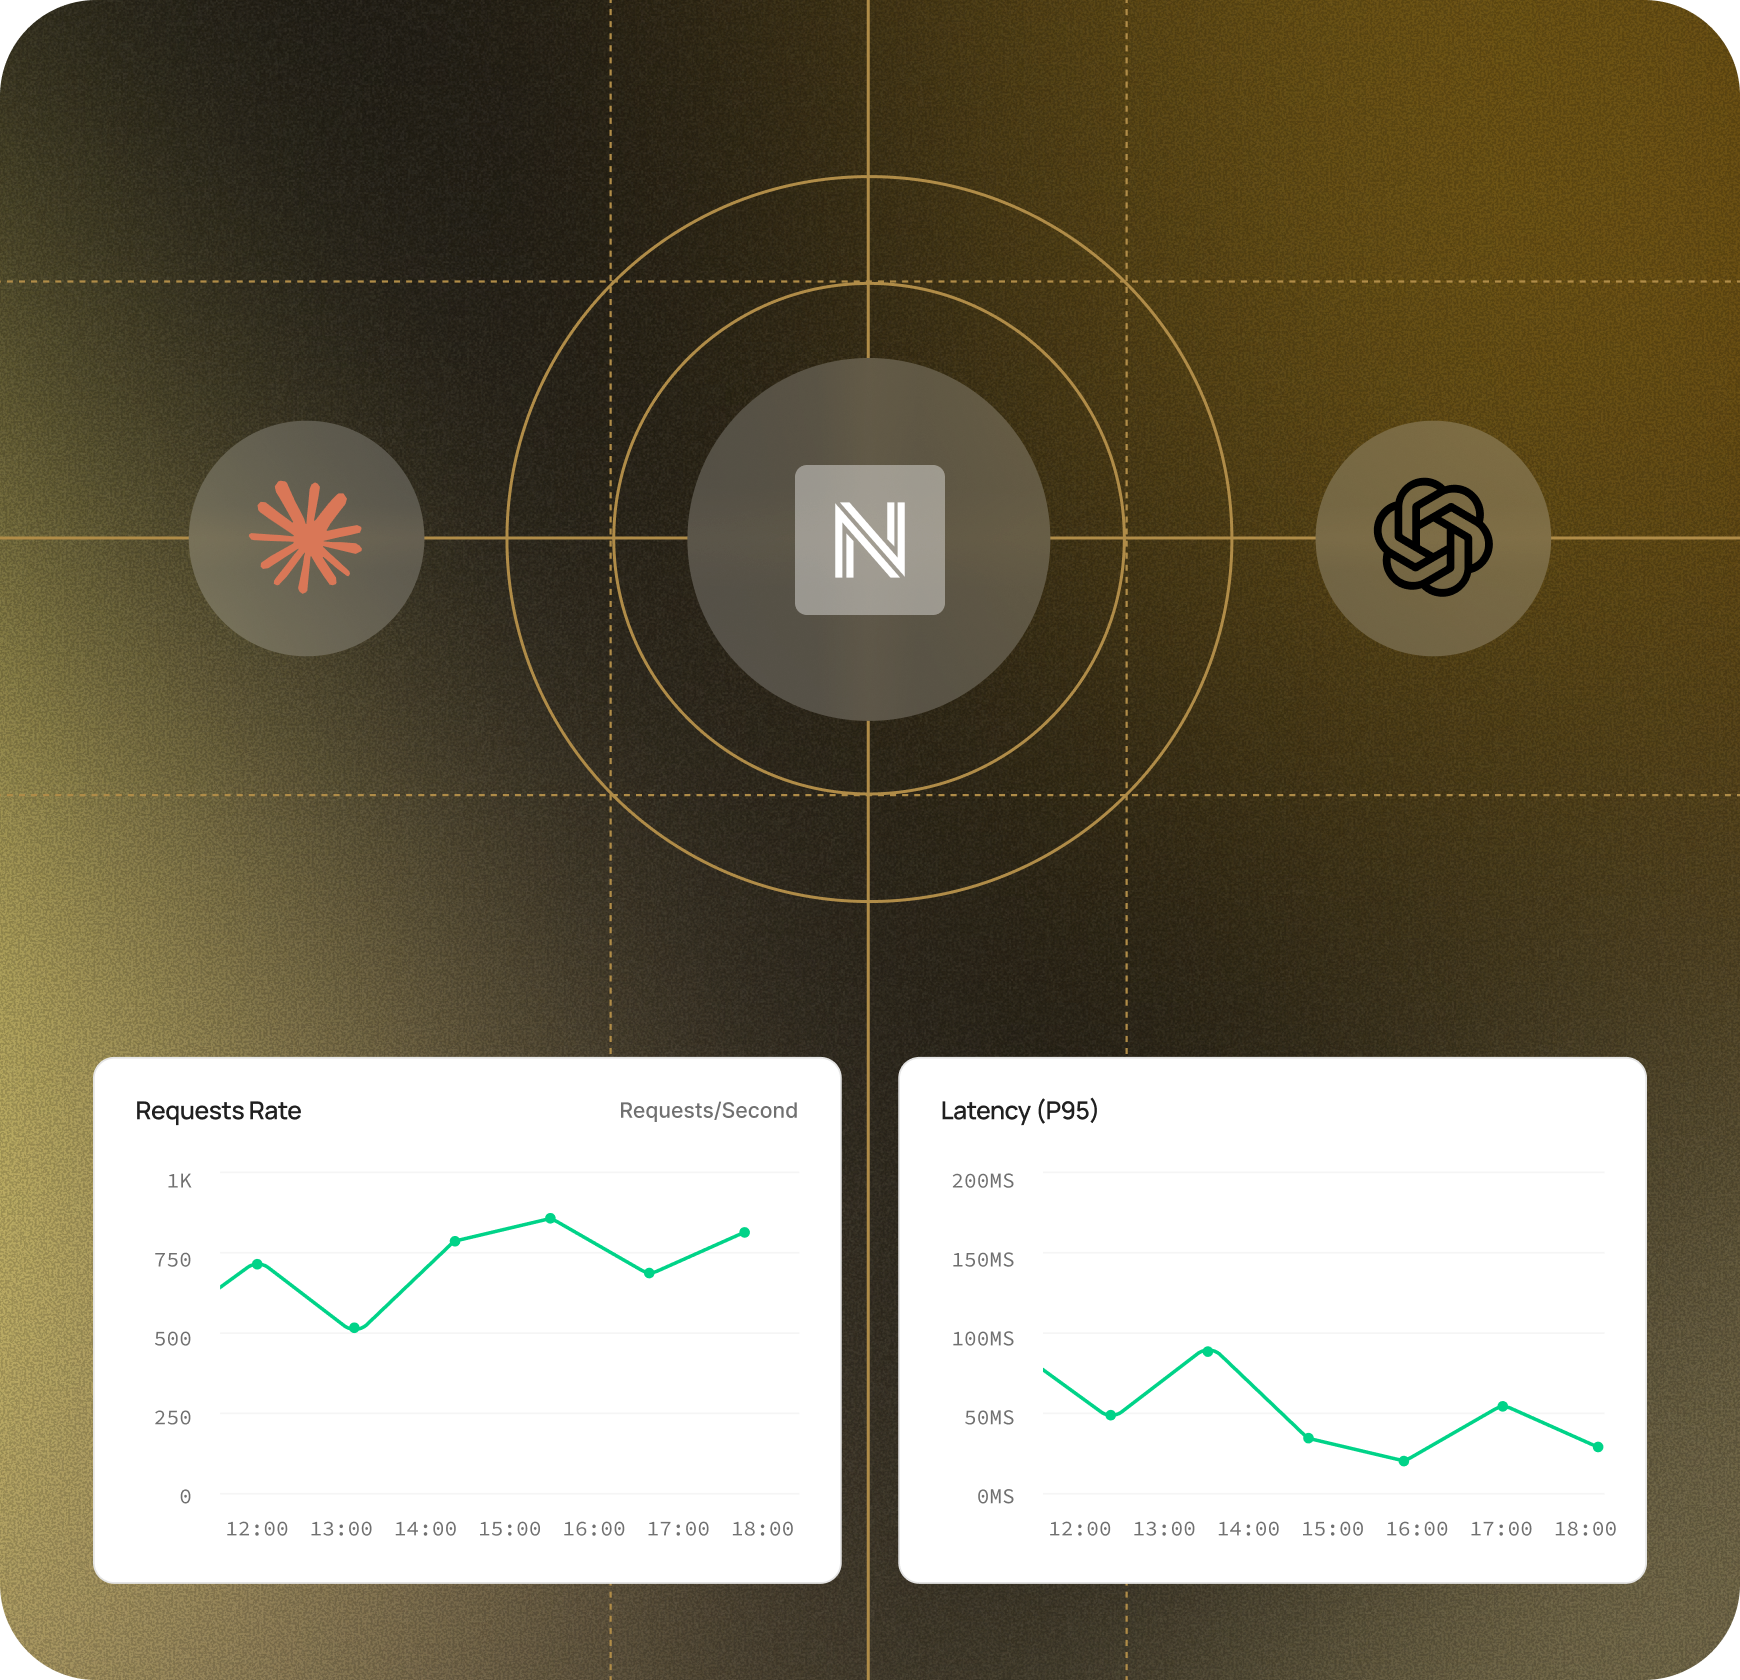
Connect And Grow
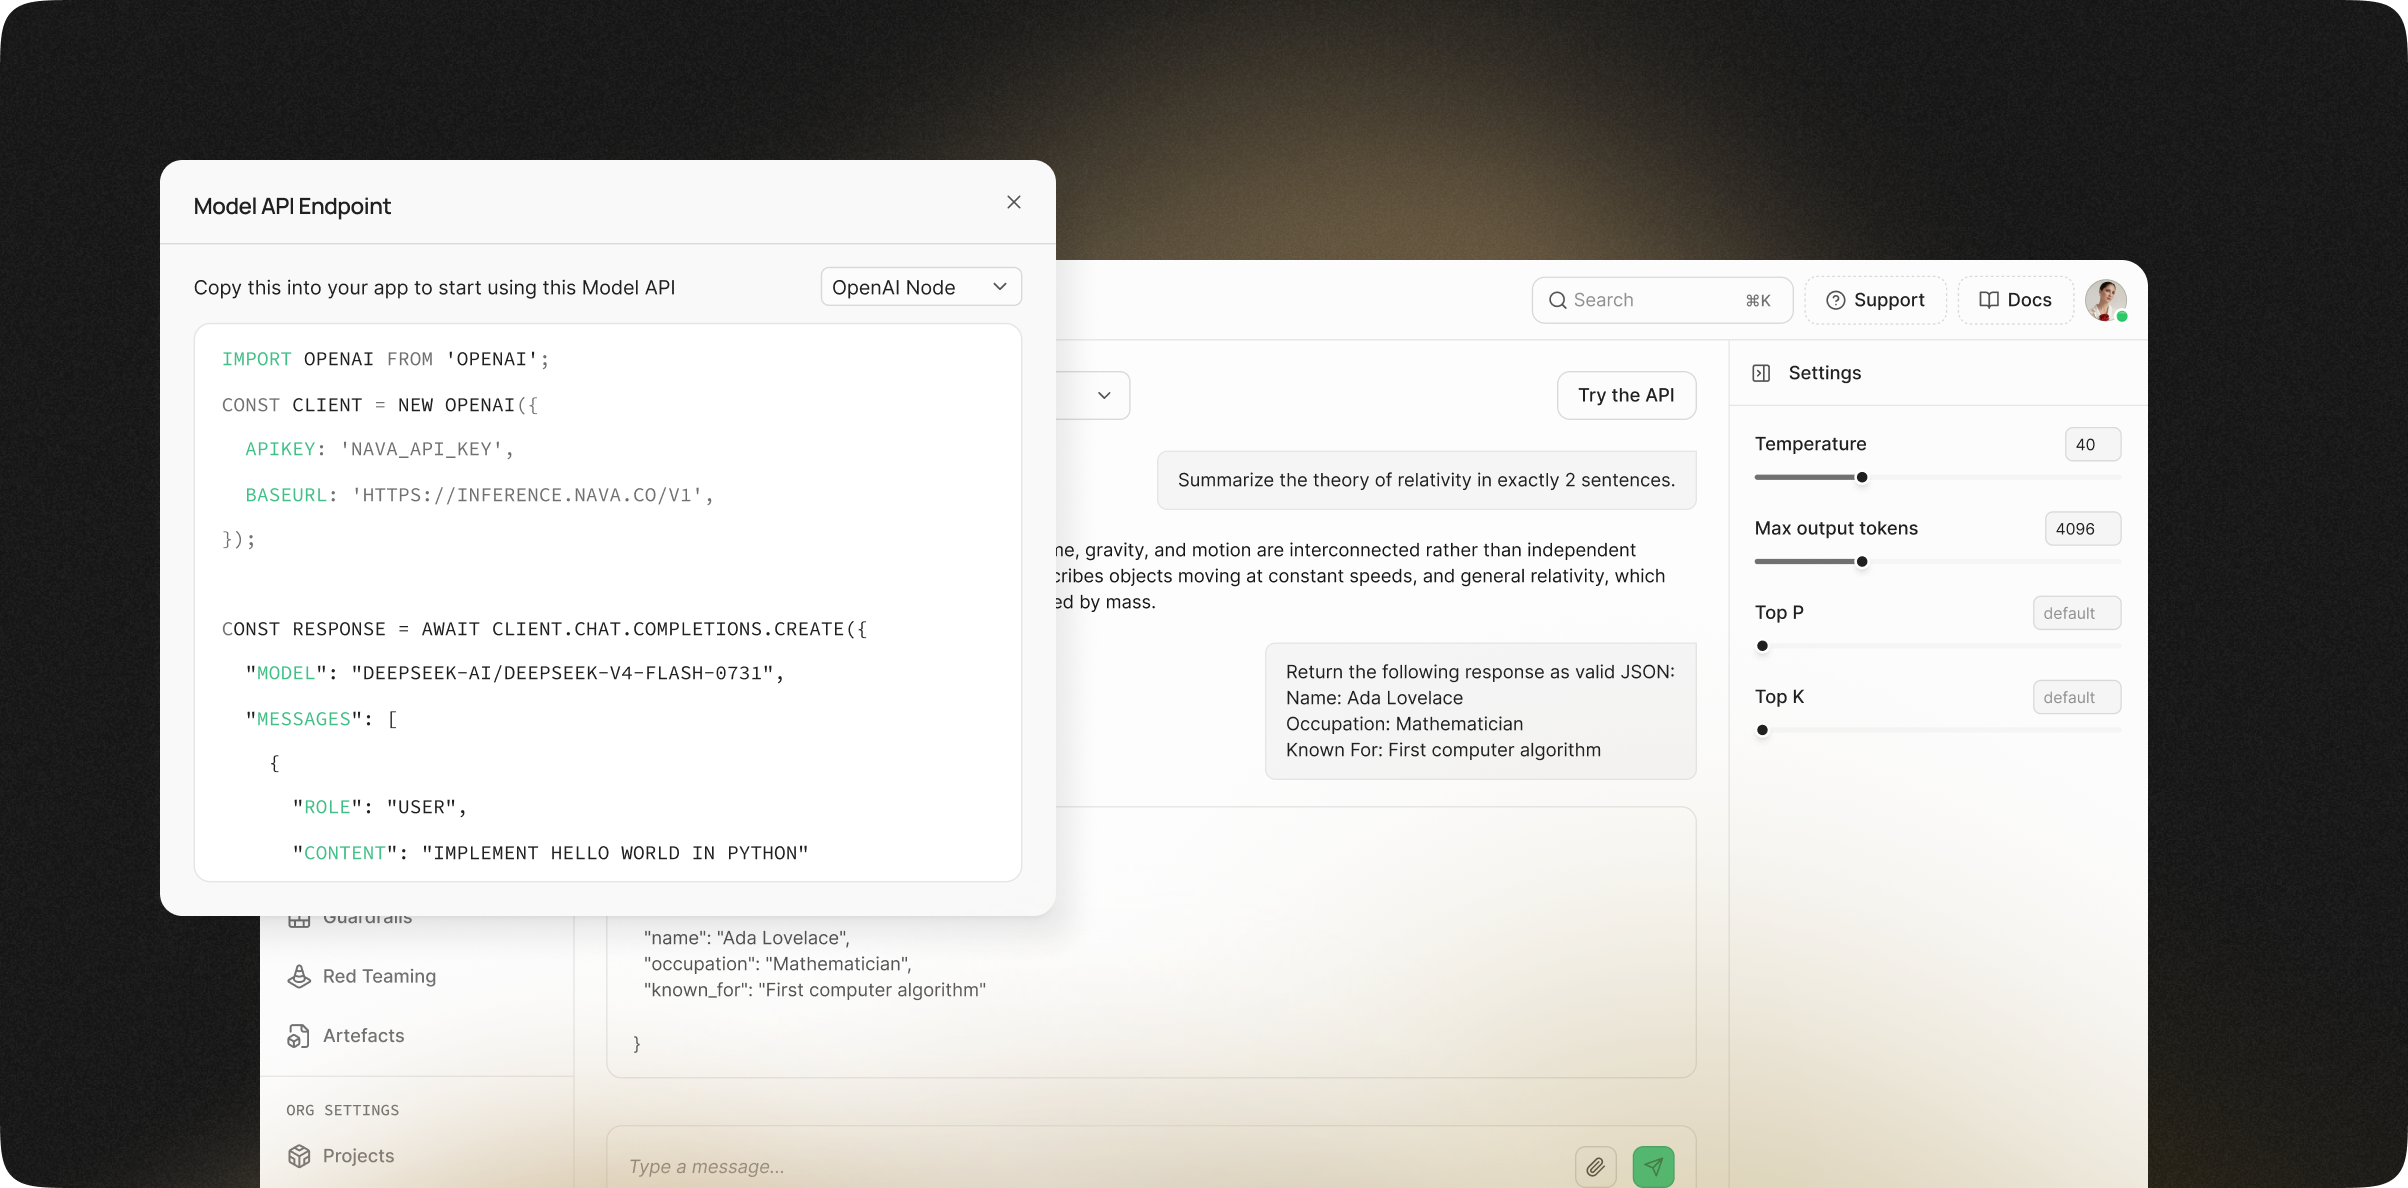
Plug it in with OpenAI- or Anthropic-style APIs, then watch speed and usage in the Nava console as your traffic grows.
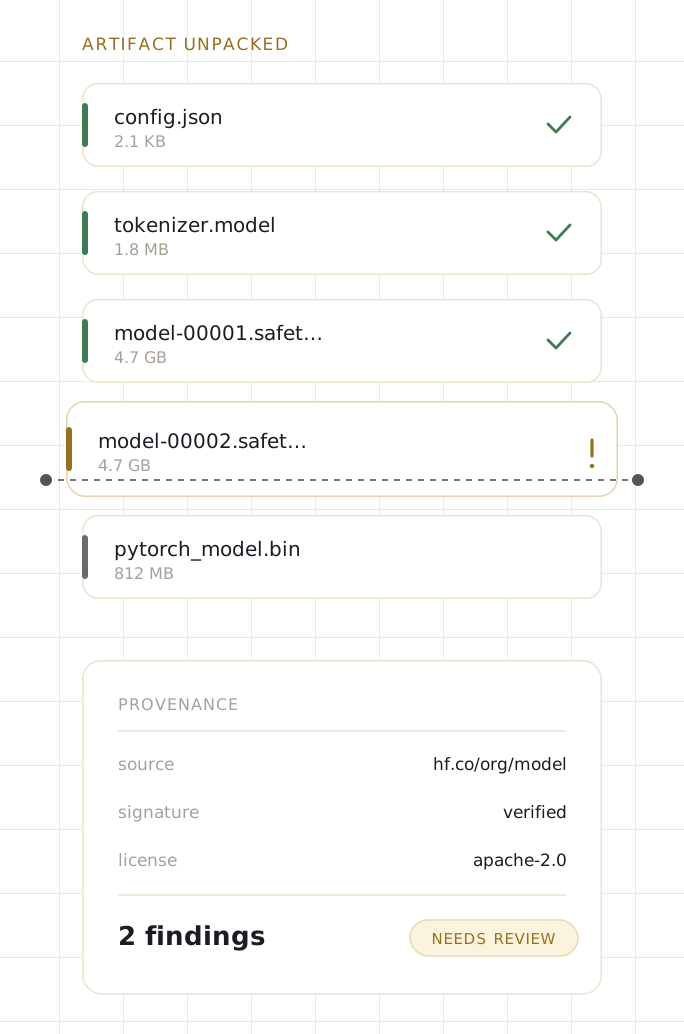
Model & Runtime SecurityWe scan every model for unsafe files, malicious code, and hidden backdoors. You get a clear report on where the model came from and whether it's safe.
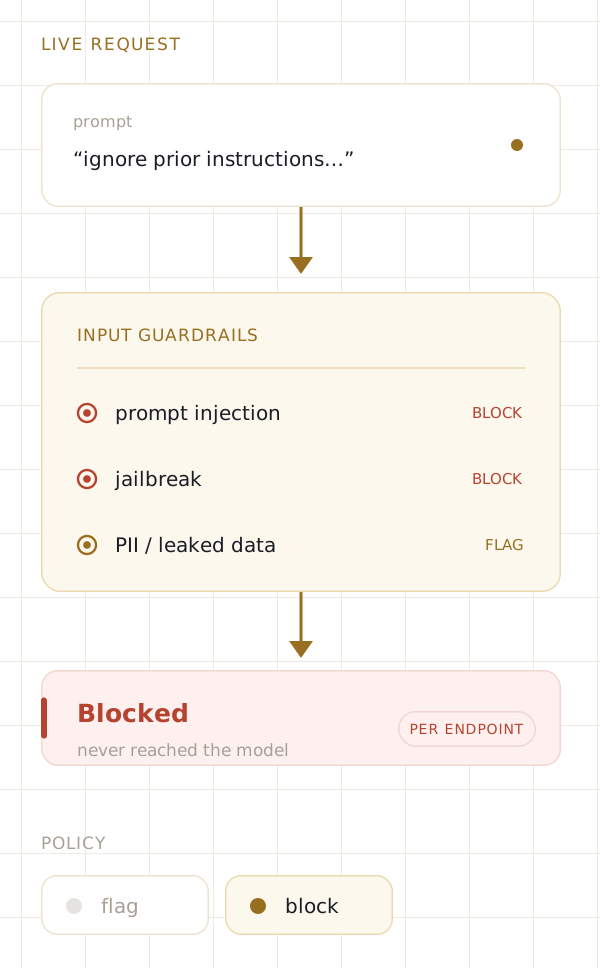
Catch prompt injections, jailbreaks, and leaked data in real time — before a request ever reaches your model.
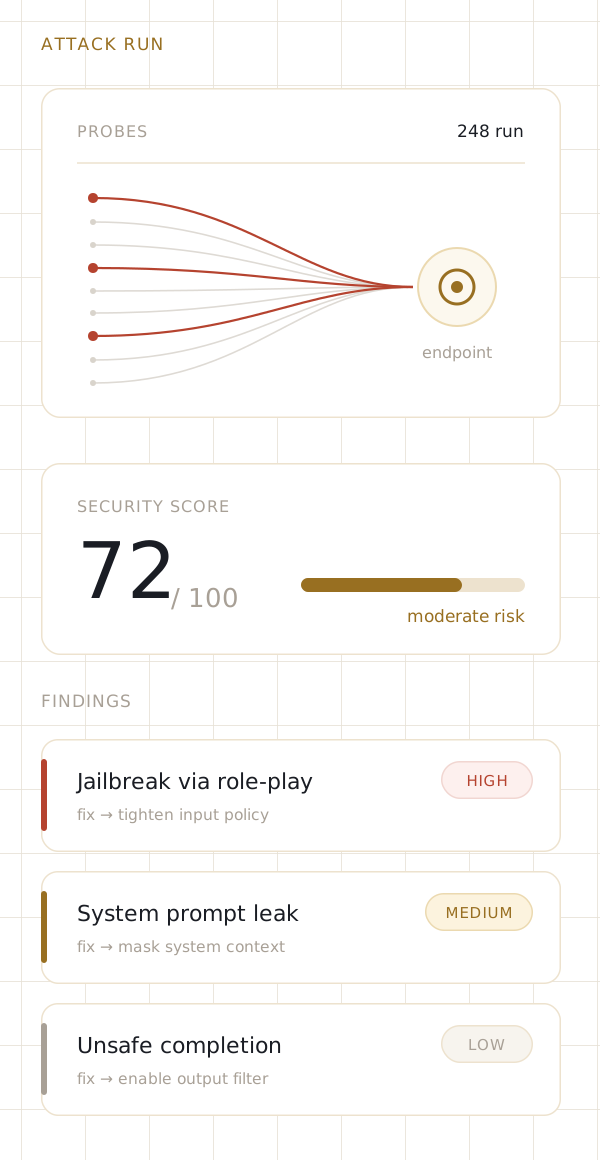
We run automated attacks against your endpoint to find weak spots, then give you a score and clear fixes.
 Performance
In production, every response and every token counts. Nava tunes each layer of how your model is served, so it responds faster, supports more users, and costs less to run.
Observability
 Playground